
TypeSafe AI is a San Francisco lab founded by former OpenAI researcher Diogo Almeida, along with Erik Gafni and Sasha Sheng. Almeida co-invented RLHF and worked on the research behind ChatGPT. The lab has released Jev, which it describes as the first System One Model.
Jev does not generate text. Instead, it returns typed, probabilistic decisions that software can act on directly.
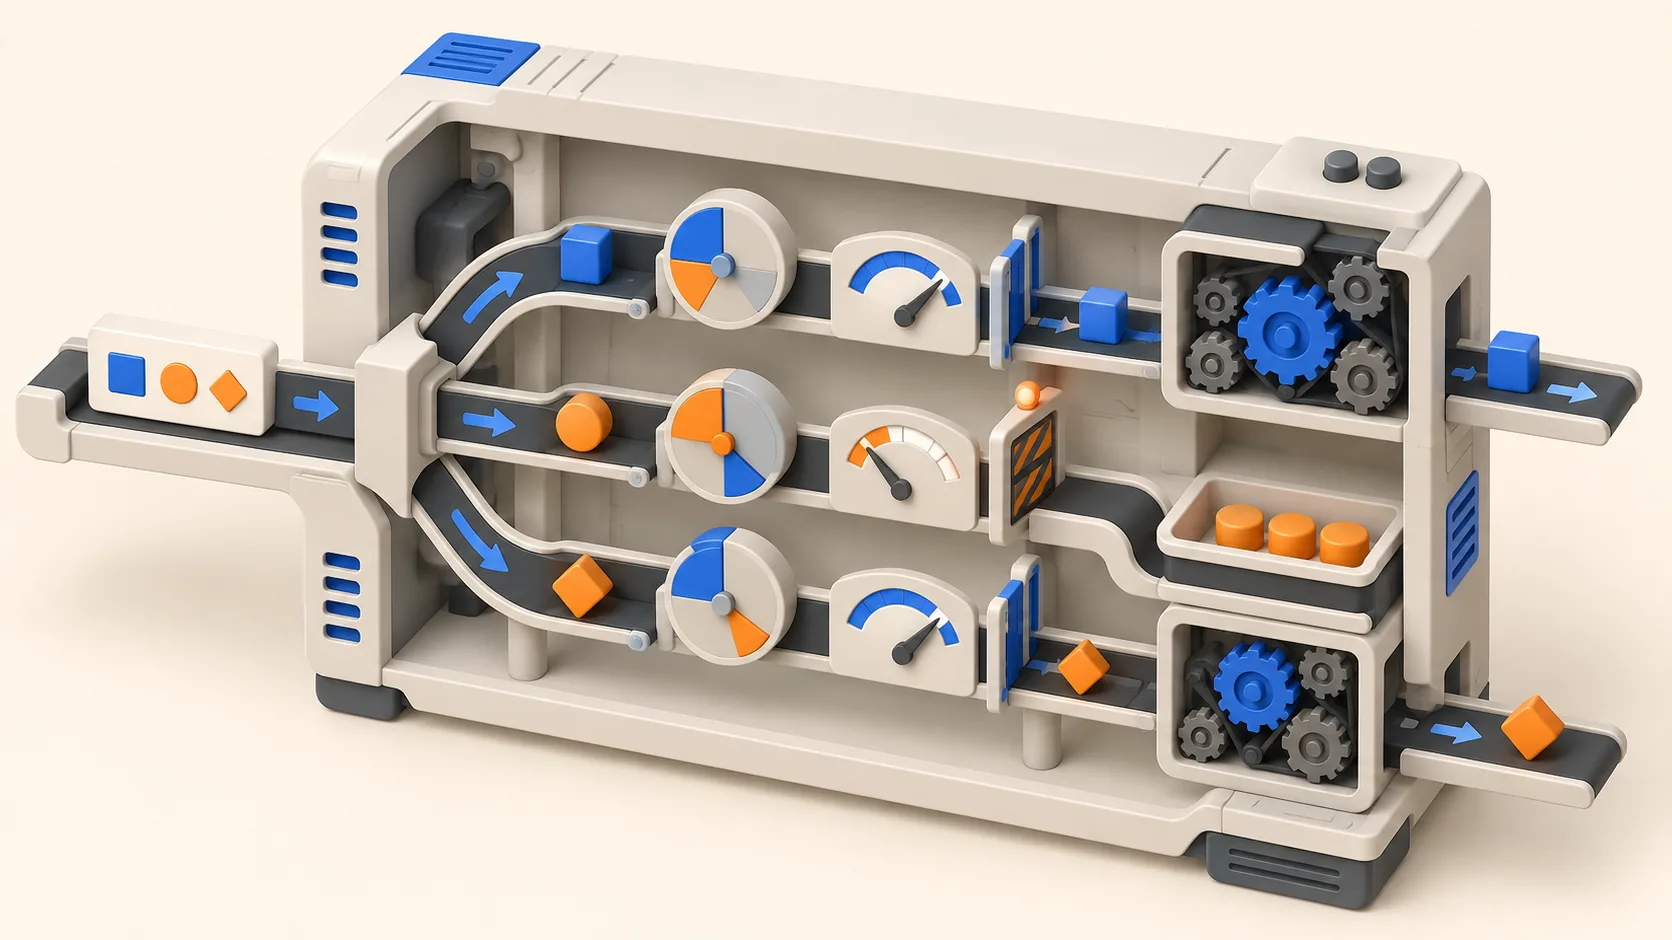
How Jev processes states and questions
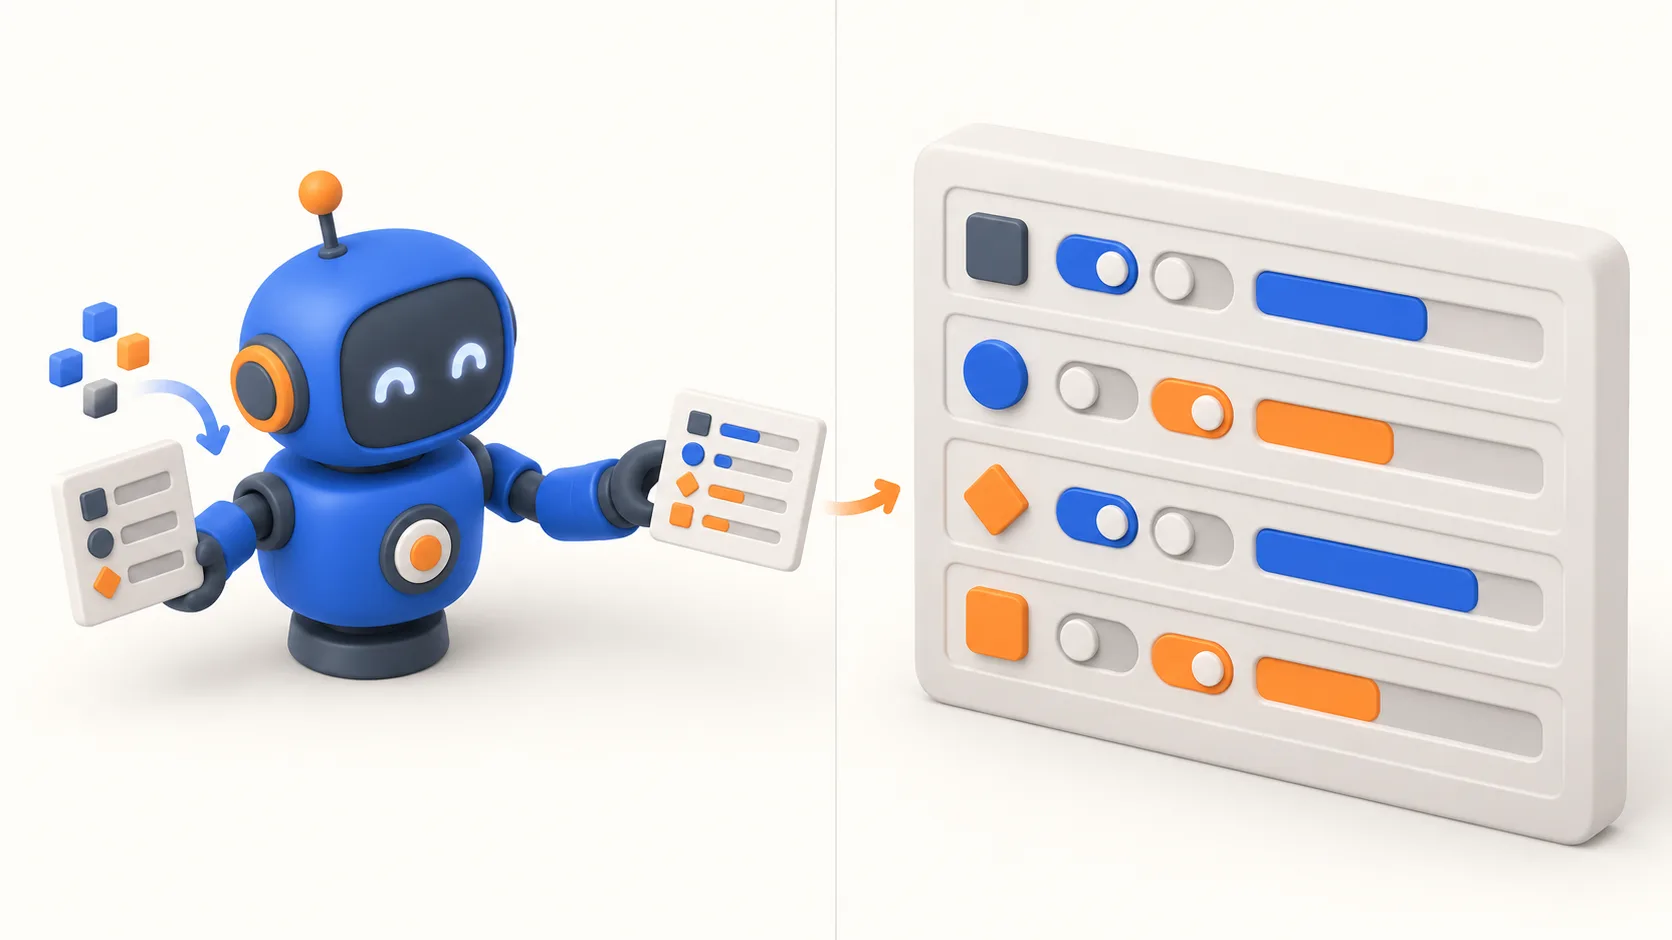
A caller sends a state as a string or structured data, combined with a set of typed questions. Jev evaluates all of them in a single parallel pass. It returns Choice, Score, and Noul answers with a probability distribution and a confidence value. Calling code can then act above a threshold and escalate below it.
Input costs $0.042 per million tokens, while output is free. The context window is 32,000 tokens, and TypeSafe quotes end-to-end latency of 70ms to 500ms. The training process uses a method the company calls Reinforcement Learning for Calibrated Decisions.
Rapid adoption and varied industry feedback
Vercel added Jev to its AI Gateway on day two. Vercel stated that Jev reached nearly 13% of paid teams within 24 hours, which is twice the share of the GPT-5.6 family. Netlify followed, and LangChain shipped a TypeSafeClassifier integration with model routing and an AutoMode middleware that screens tool calls before they run. Five independent Elixir clients also appeared within days.
Vercel engineer Pranit Sharma found that a safety classifier ran five to 18 times faster than the LLM it replaced. Bryo AI CTO Nikhil Mudholkar rated Gemini slightly more accurate on email classification but 10 to 20 times more expensive, and valued Jev as the only model handing back a real probability. Armin Ronacher, CTO of Earendil, told TechCrunch that the design delegates the hallucination problem a little bit to the user, who must decide if a 50% probability is worth acting on, and pointed to model routing as another good fit.
An analysis of 12,759 launch tweets by OpenChamber put user-reported speedups at a median of 7x against the 193.6x headline, cost savings at a median of 30x, and latency at a median of 76ms with an upper quartile of 270ms. One developer on Reddit called the model absolutely insane for agent work at 200ms to 300ms latency. An early access user on Hacker News called it really neat while cautioning that its out-of-distribution behaviour will differ from an LLM.
On Hacker News, one developer noted that Jev cannot emit an invalid type but can still emit a completely wrong valid value. Another commenter suggested a more accurate title would be trading general purpose generation for fast typed inference, noting that Jev can only generate structured output rather than general code.
 Read nextOpenAI and Synopsys Partner to Build AI Chip Design Model
Guidance for teams replacing LLM classifiers
Teams replacing LLM classifiers should start with the jev-1.13 jaggedness page. This page documents unreliable counting, arithmetic, and date comparison, alongside accuracy loss on large noisy state, and advises keeping math in code.
Users should pin a version such as jev-1.13.0 rather than using the moving jev-latest and jev-preview aliases. Teams should also use the System One adapter to run existing models against the same schema when benchmarking, and consult the quickstart for keys, SDKs, and the playground.