
Reka AI has released a research preview of Rho-1. The 19-billion-parameter omni-model processes and generates text, images, video, and robot control actions in a single neural network.
Unlike most AI systems that route tasks to specialized models, Rho-1 runs all modalities as tokens in one shared context window with no tool calls or external models. The model generates continuous video in real time and responds to new instructions on the fly without restarting.
Shared weights drive camera and robot tasks
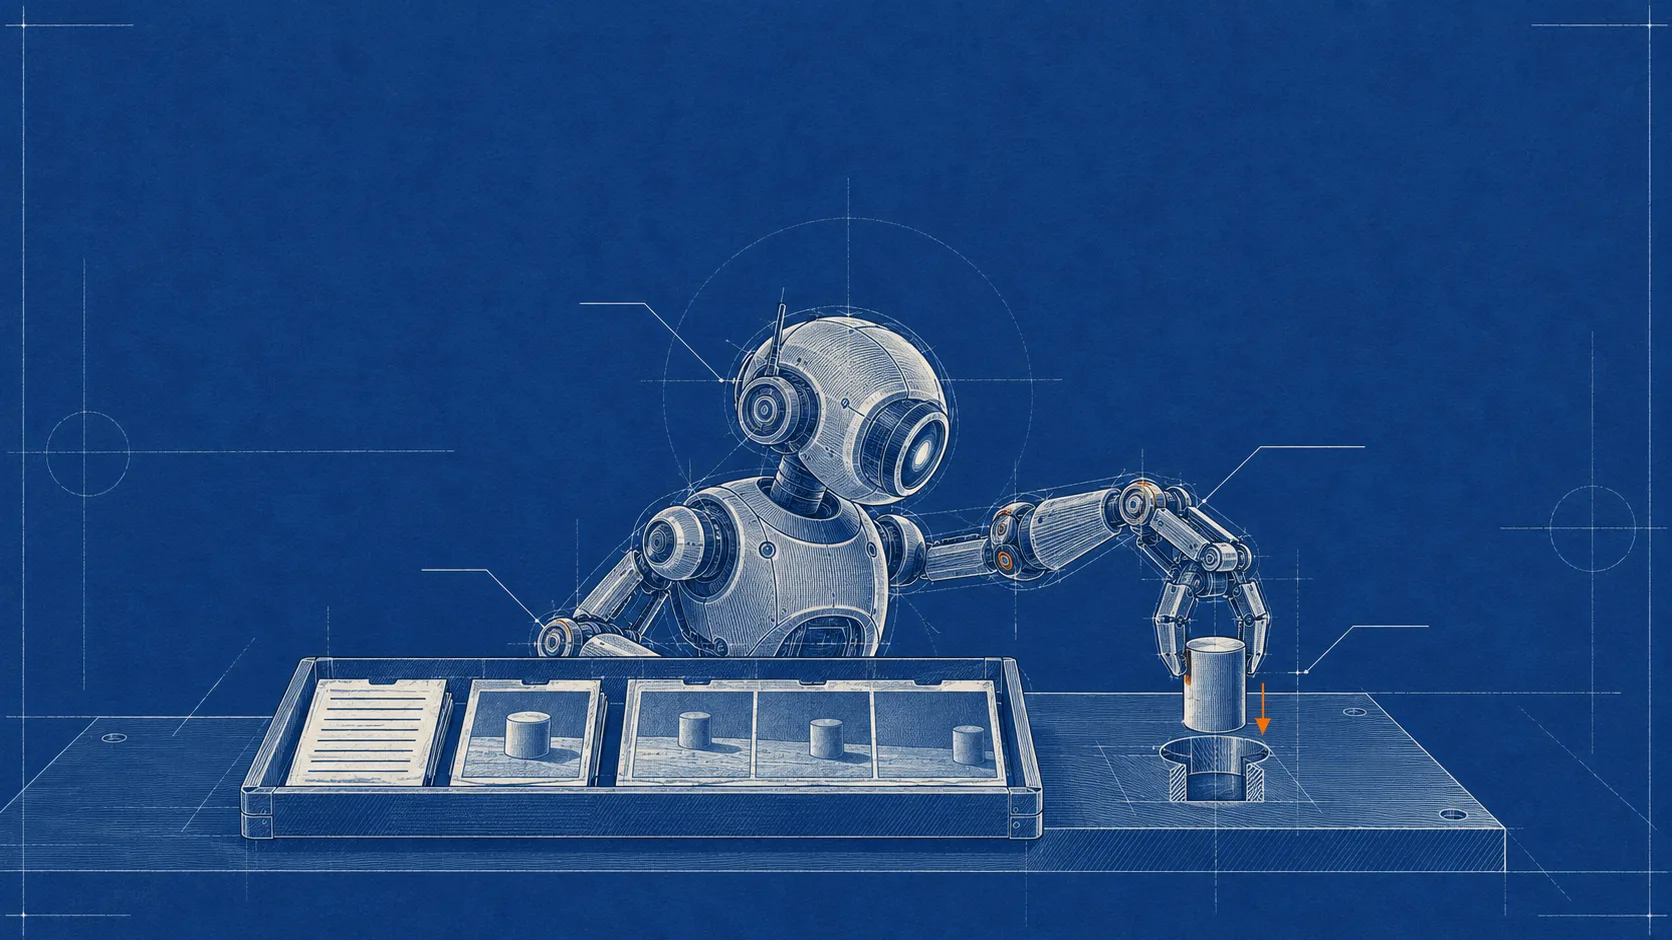
The same weights that predict camera images also drive robot movements. To work around scarce robot training data, Reka AI built an inverse dynamics model that pulls control signals from ordinary internet videos. Rho-1 trained on 320 H100 GPUs over about three months.
Reka AI is not new to multimodal AI. In April 2024, the company shipped Reka Core, a multimodal language model that competed with GPT-4, Claude 3, and Gemini Ultra on benchmarks. The release fits a broader push in AI research toward so-called world models.
Reka AI released a research preview of Rho-1 as the next step in its multimodal development.