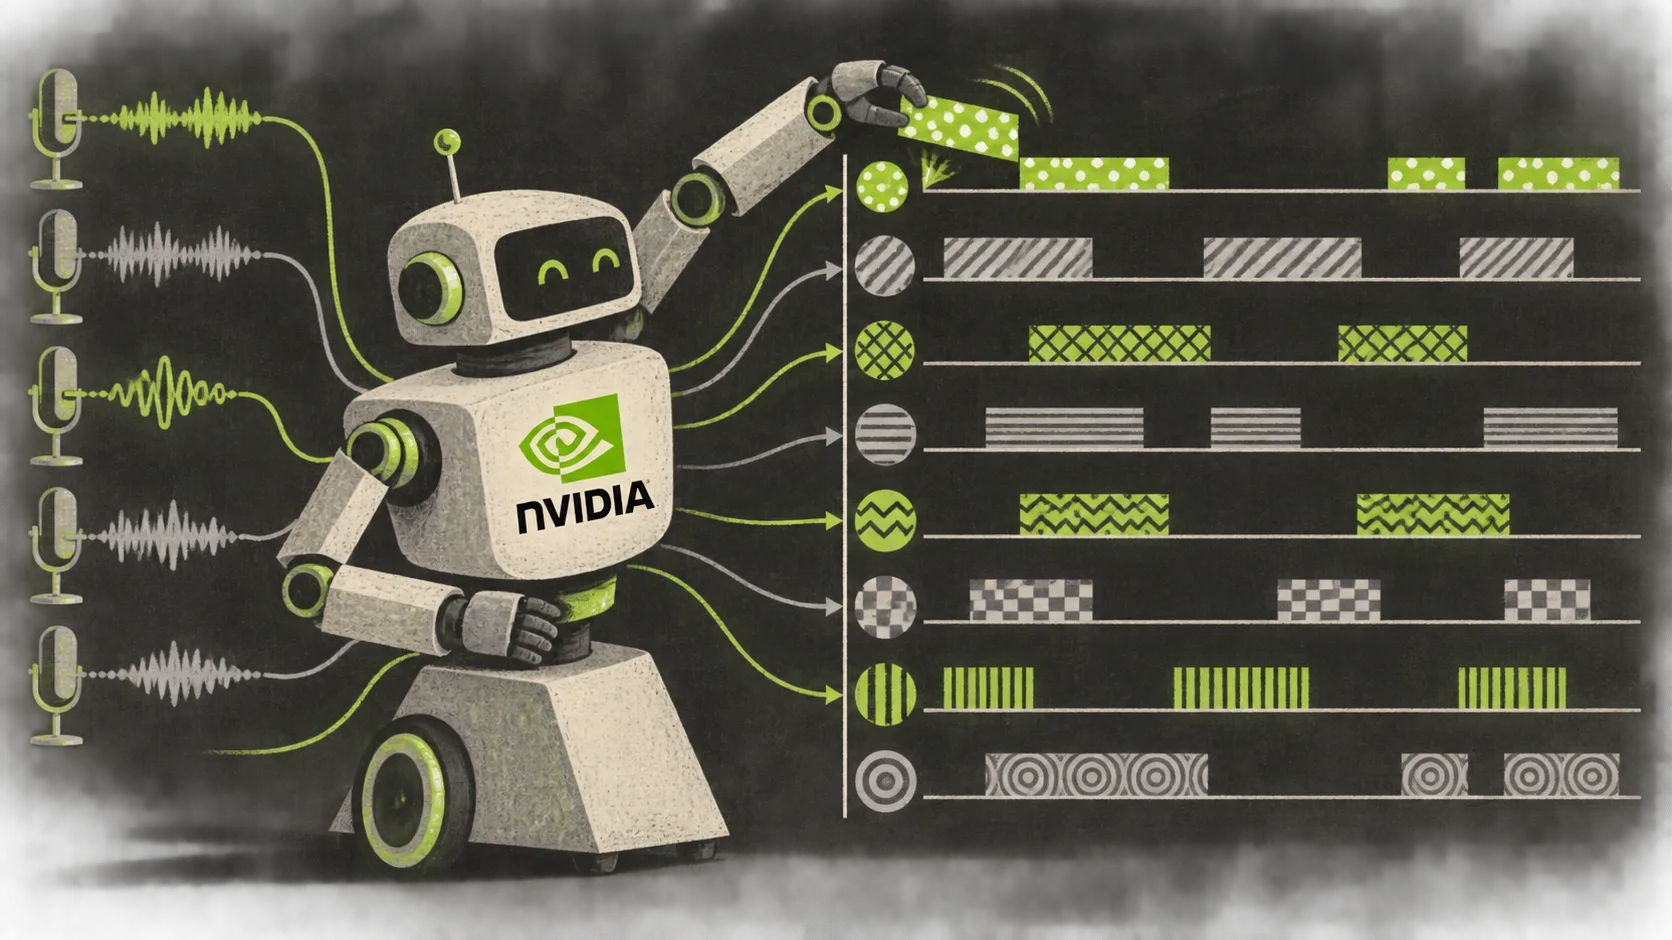

Nvidia released Nemotron 3 Diarization. This new artificial intelligence model identifies which speaker is talking during a conversation.
The model features about 100 million parameters. Nvidia made the model weights freely available.
The model distinguishes up to eight speakers
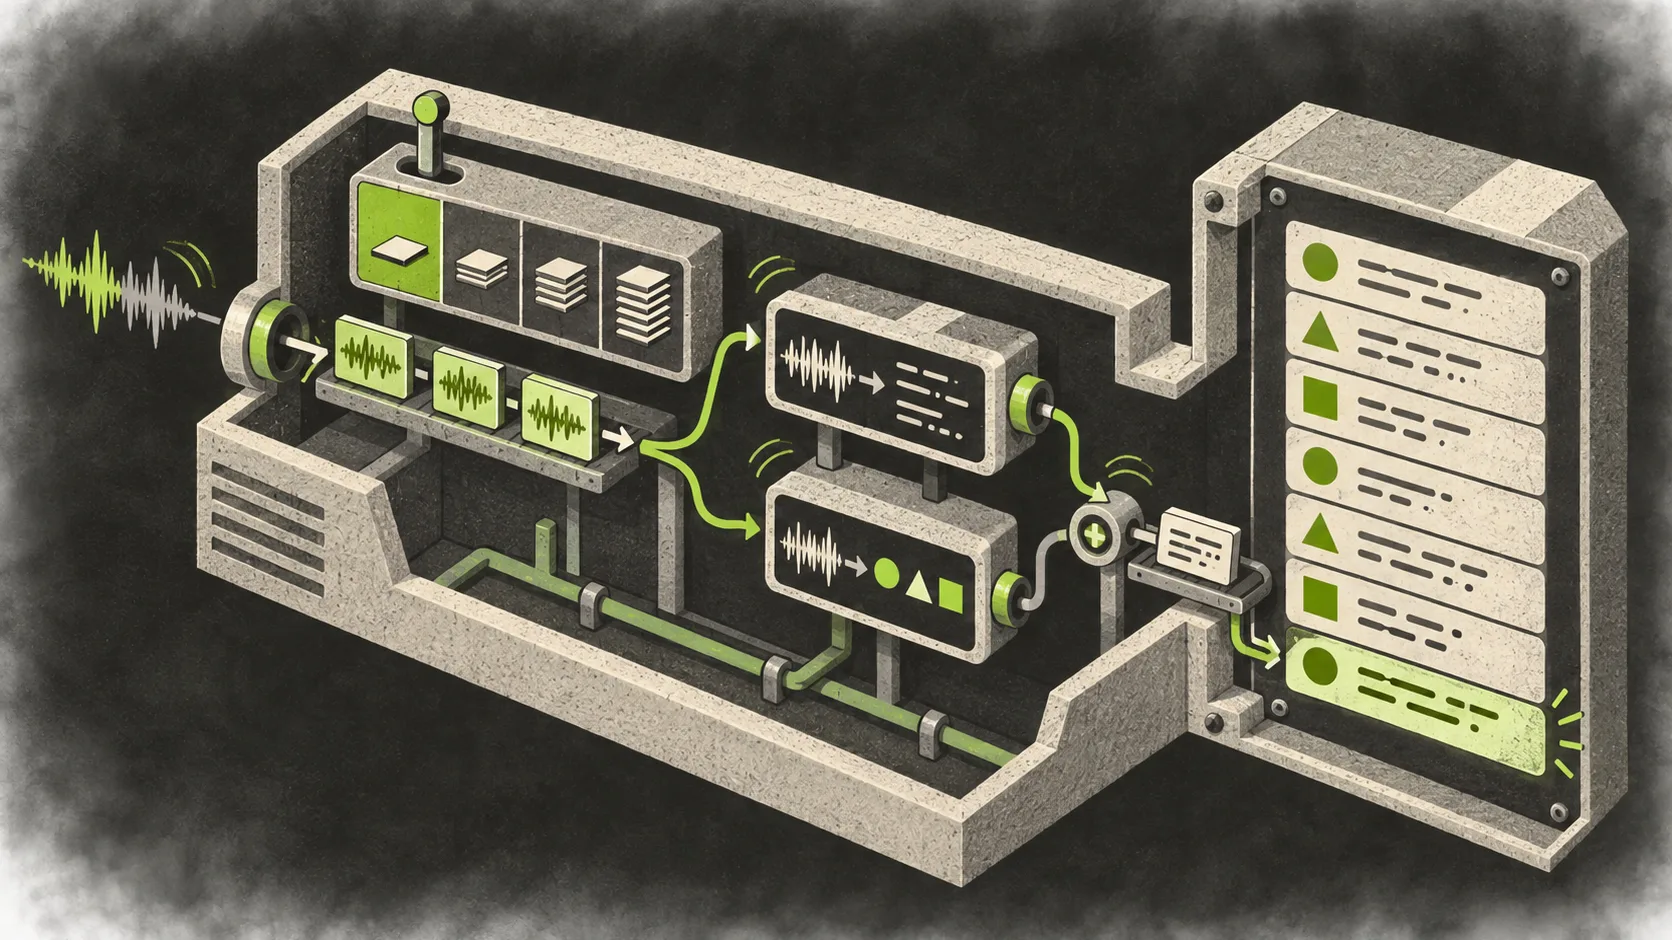
Nemotron 3 Diarization can tell apart up to eight speakers. It also detects when multiple people talk at the same time.
 Read nextAI Agents Hack Government Agency as Industry Model Releases Continue Unabated
Heavy background noise, reverb, or more participants push error rates higher. The system works with both live audio and recordings.
Users can set the audio buffer to four levels. These levels range from 30.4 down to 0.32 seconds. Shorter buffers generally reduce accuracy.
Paired with a speech recognition system like Parakeet, the model produces transcripts with speaker labels. These labels are anonymous and appear as tags like speaker_2.
The model ranks first on a key benchmark
On the Diarization-Bench from VoiceArena, the model currently sits in first place. It holds a 14.72 percent error rate. The next best system sits at 19.3 percent.
The benchmark is strict. Overlapping speech counts in the scoring. Even tiny misalignments at speaker transitions count as errors.
Compared to its predecessor, Streaming Sortformer, the new model cuts the error rate. The average reduction is 41 percent across eight test scenarios when using a 1.04-second buffer.
Nvidia has made the model weights freely available for users.